MiniMax
M3.1 Flash
MiniMax’s new fast model. It builds a full web page for under 2¢.

- $0.15 / $0.60
- per 1M tokens, in / out
- 1M
- tokens of context
- #5
- of 174 on Artificial Analysis
- 330 tok/s
- on Together AI
117× cheaper than Opus 5.5.
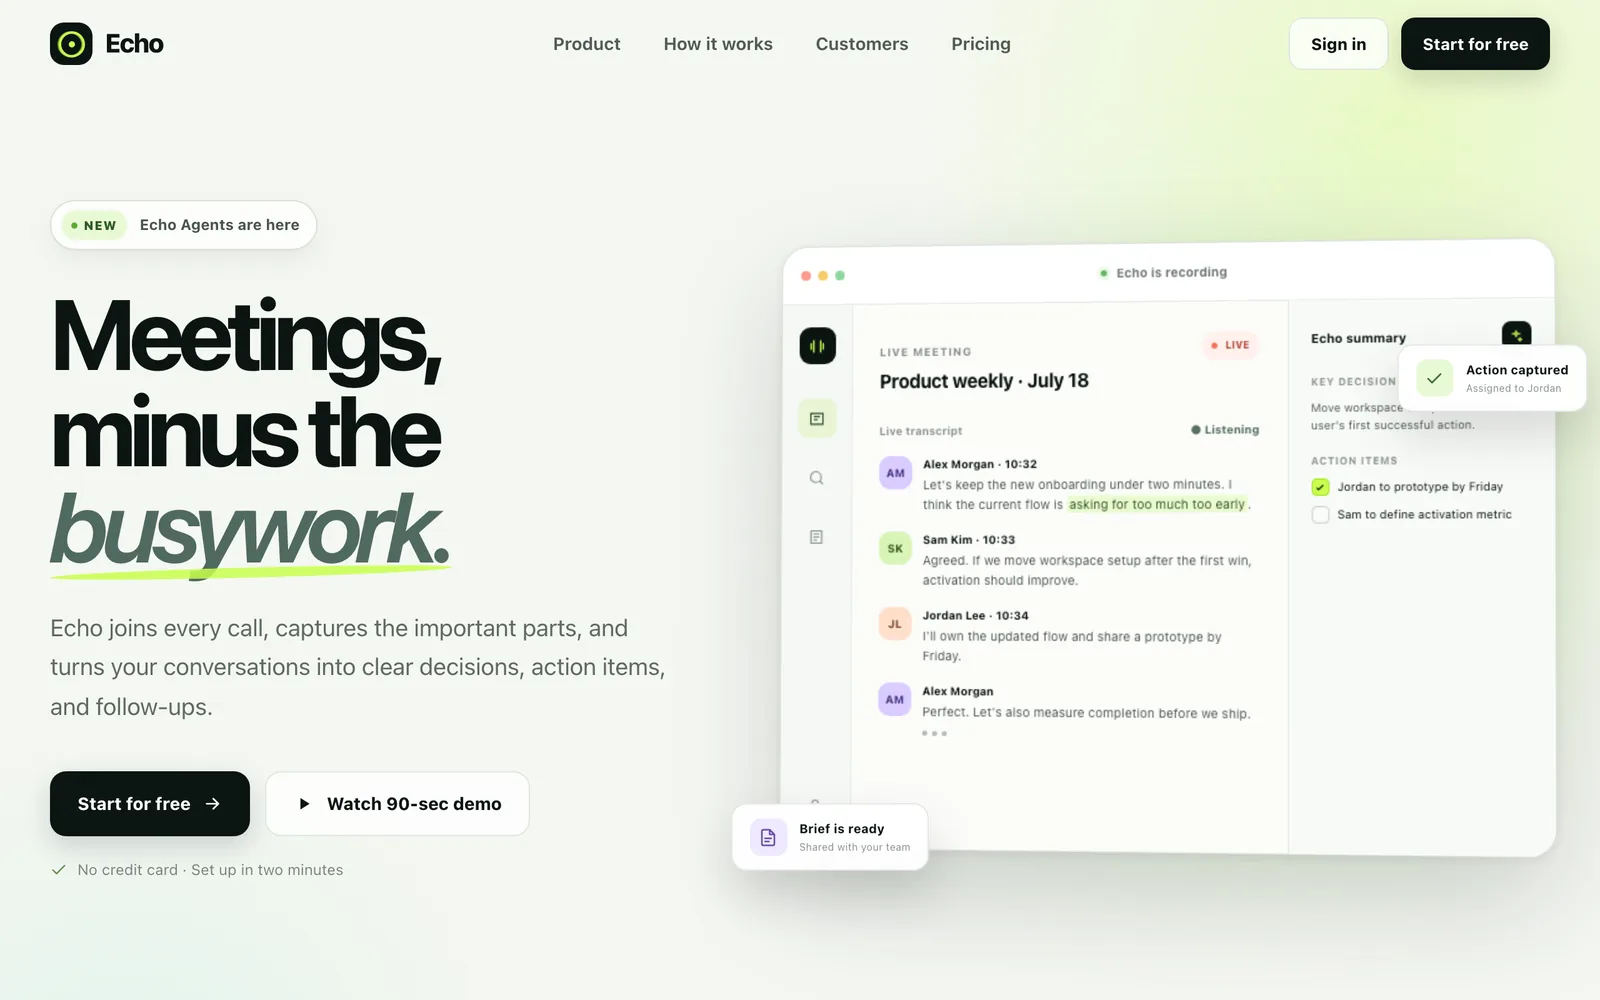
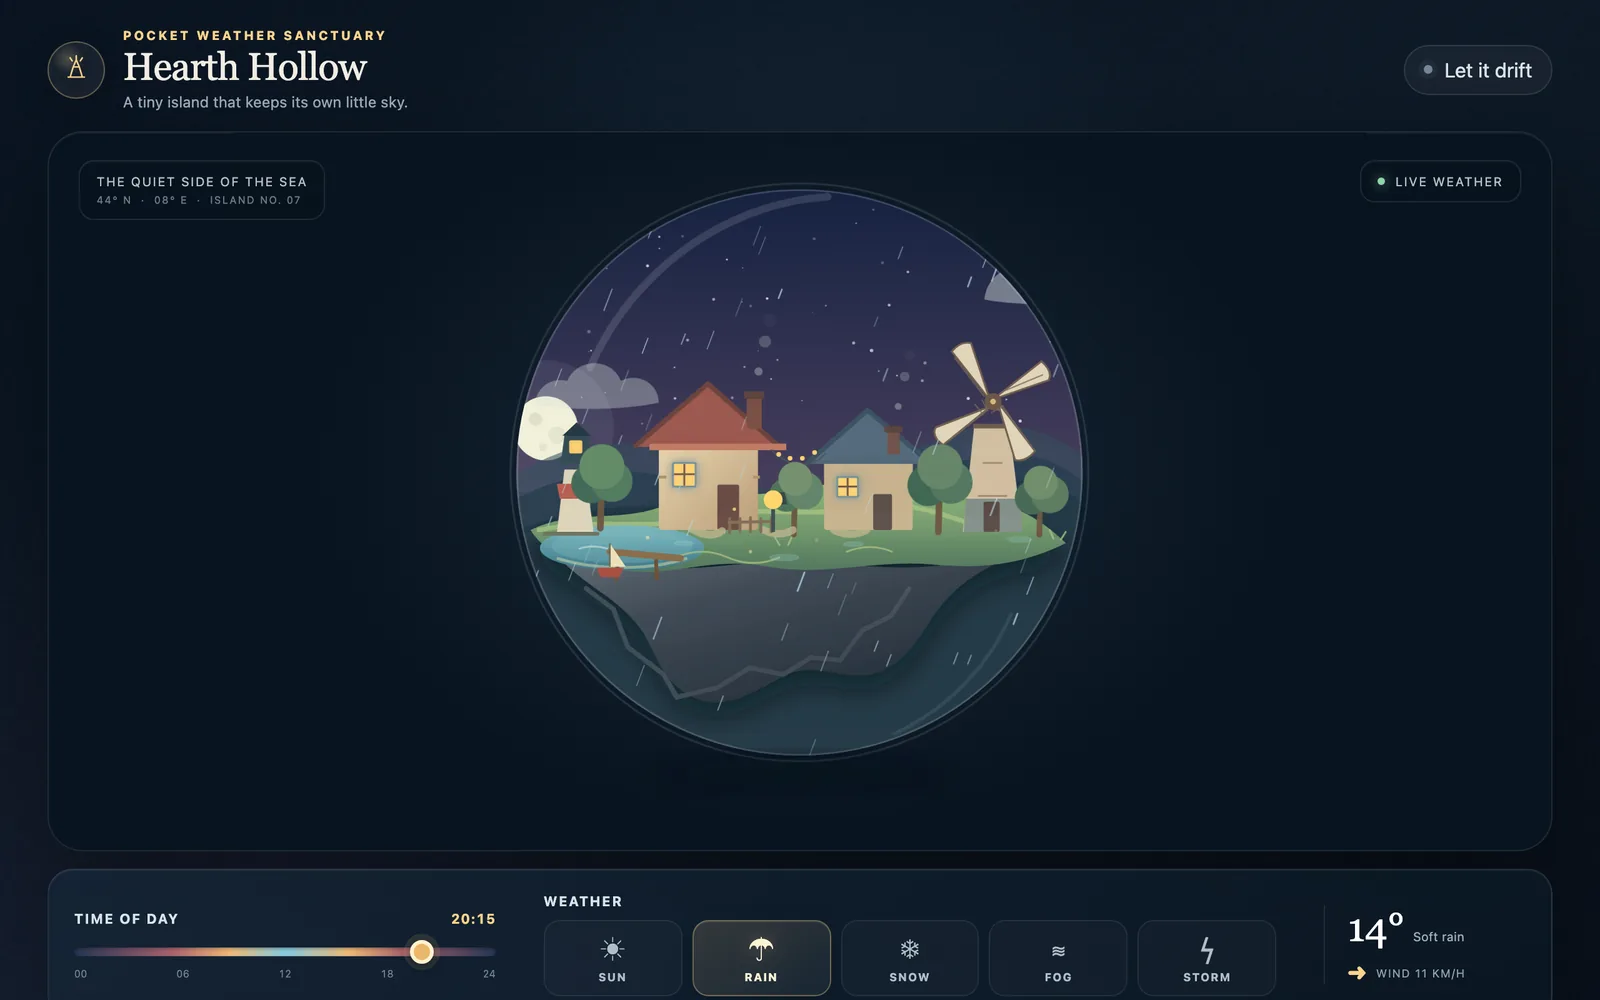
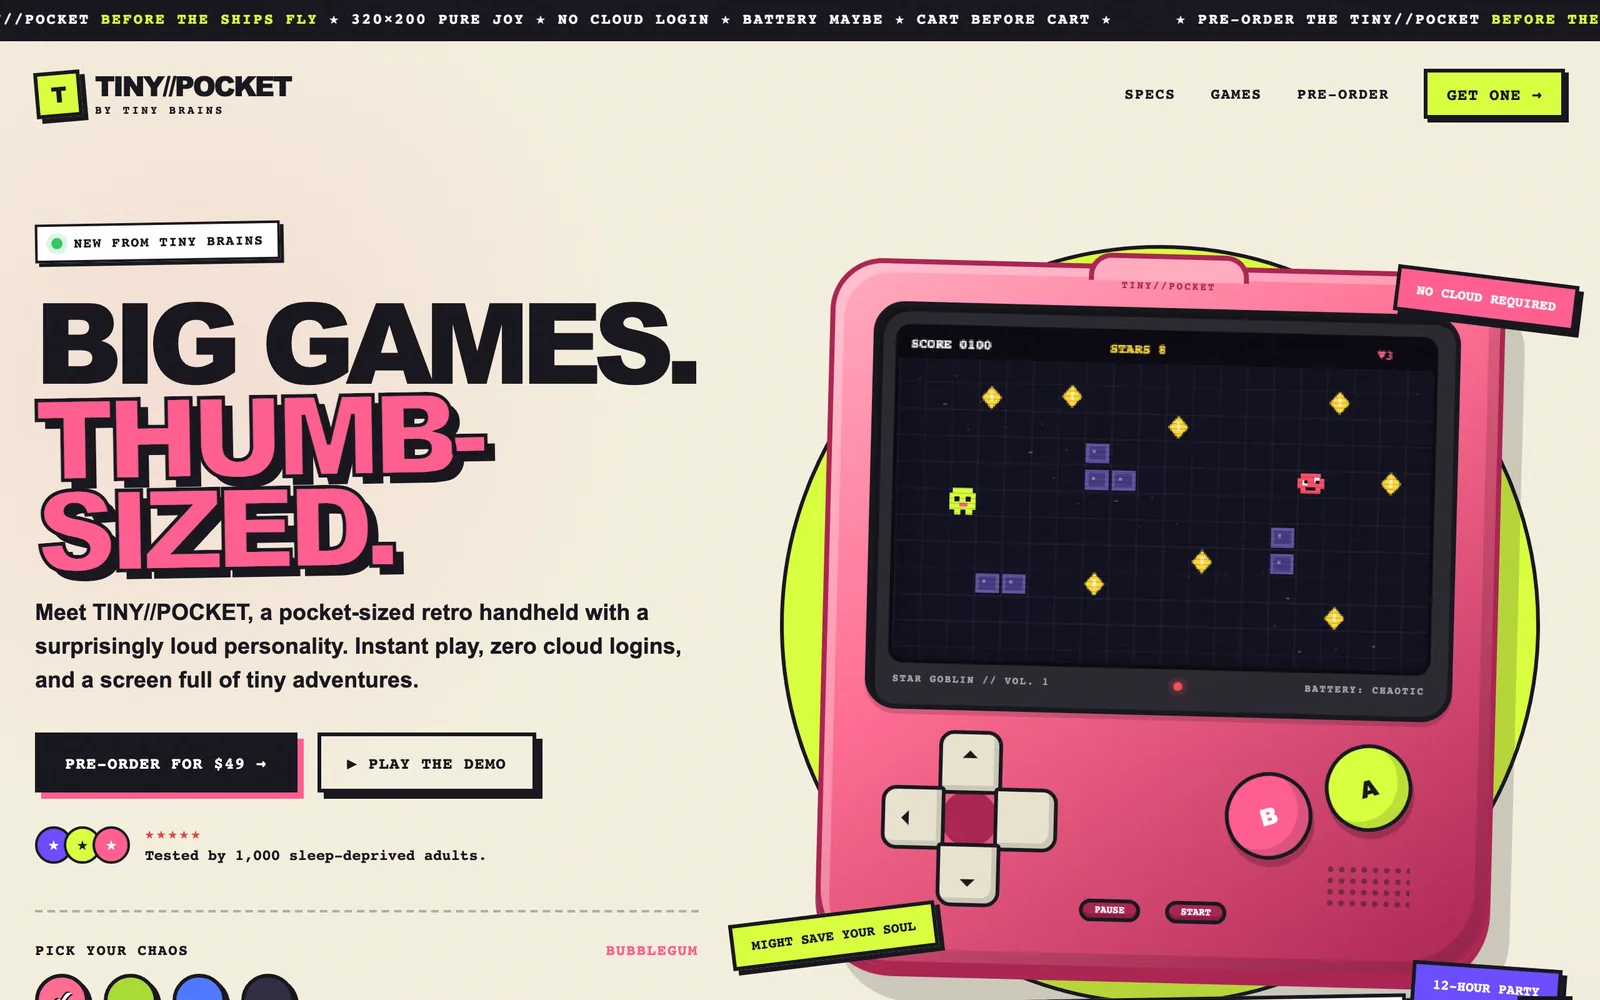
Same prompt, two models, 11 times. Open any build and click around.
vs Opus 5.5
117× cheaper
5 builds, faster on all 5
vs GPT-6 Astra
76× cheaper
3 builds, faster on all 3
vs DeepSeek V4.1 Flash
2.5× cheaper
8 builds, slower on 7
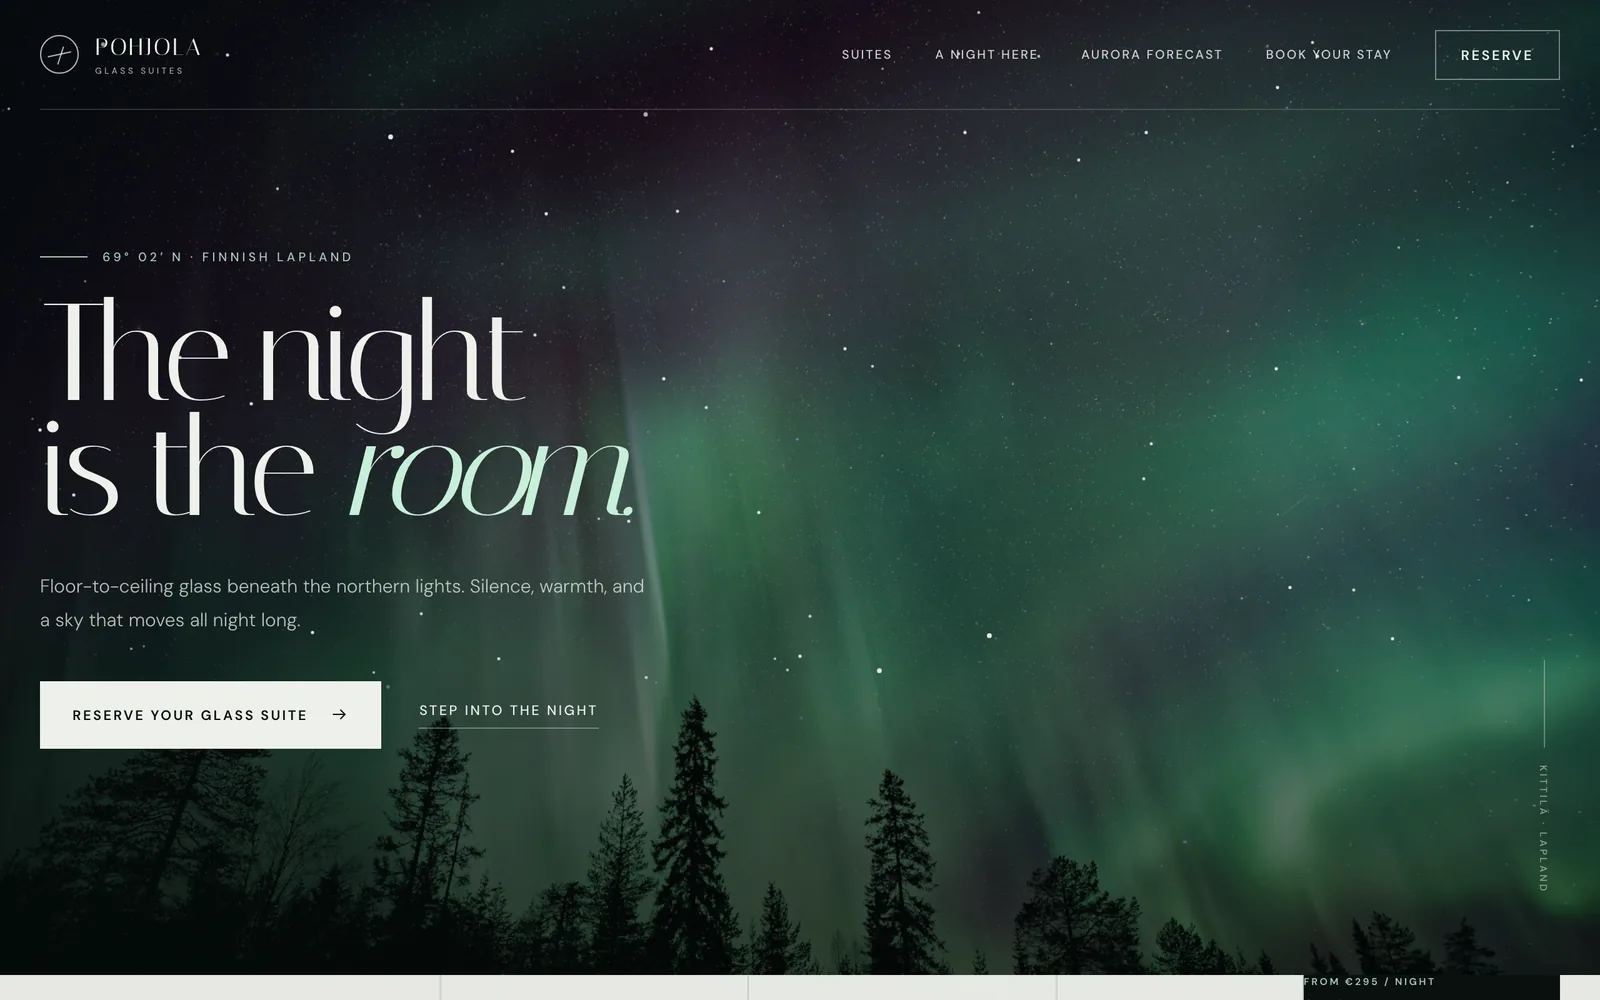
Aurora lodge
Prompt: A landing page for a lodge in Finnish Lapland where every room is a glass igloo for watching the northern lights. The hero should be a night sky with a living aurora rippling over snowy pines. Below it: the rooms, what a night there feels like hour by hour, a small aurora forecast for the next few nights, and a booking section where picking dates updates the price. Make it feel cold, quiet and expensive.
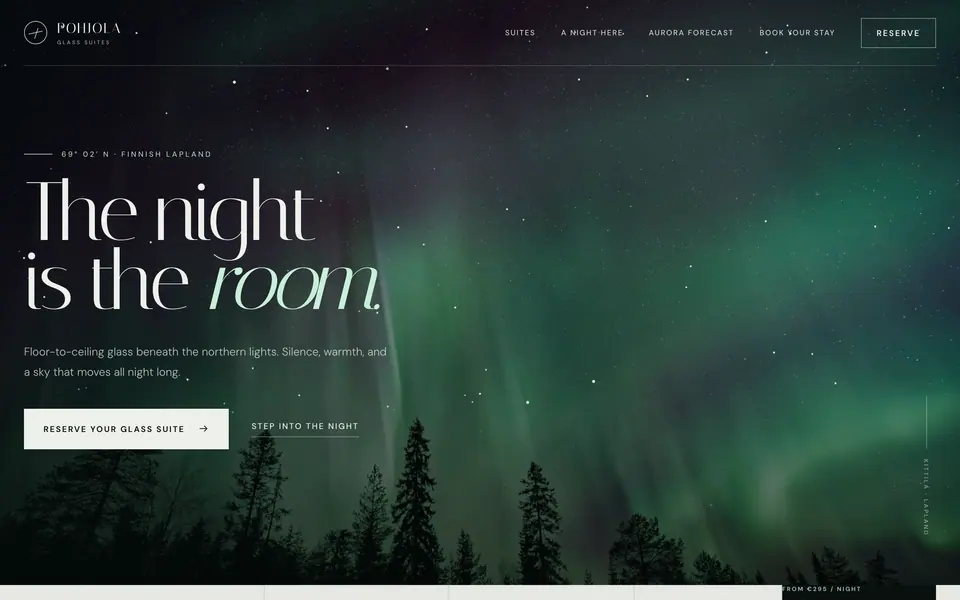
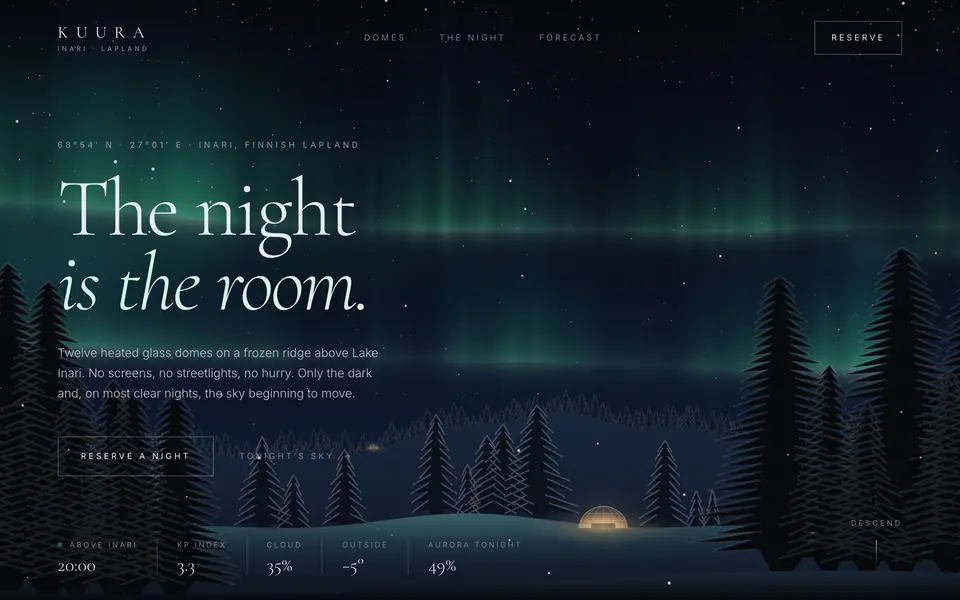
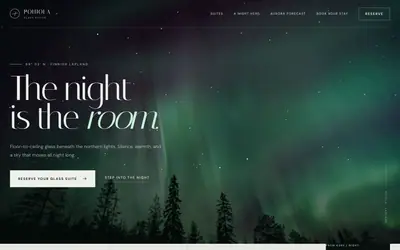
Cost is list price for the tokens each run used. Times come from MiniMax’s own API at launch, which ran at about 154 tok/s; Together AI serves it at about 330.
22¢ per task.
Cheaper than every other fast model here, and #5 of 174 on intelligence.
- 1MiniMax M3.1 Flash$0.22
- 2DeepSeek V4.1 Flash$0.26
- 3GLM-5.3 Flash$0.28
- 4MiniMax M3$0.51
- 5Gemini 3.8 Flash$1.24
Artificial Analysis Intelligence Index and cost to run it, October 2026.
What a month costs.
Pick a workload or set your own. Input it has seen before is 90% off.
On M3.1 Flash
- 360M fresh in × $0.15
- $54.00
- 2,040M cached in × $0.015
- $30.60
- 150M out × $0.60
- $90.00
Same traffic elsewhere, no caching
- MiniMax M3.1 Flash$450
- DeepSeek V4.1 Flash$900
- Kimi K3$9,450
- Claude Opus 5.5$12,600
- GPT-6 Astra$31,500
28× less than Opus 5.5, before caching saves another $275.
Run it on Together AI.
Python, TypeScript or cURL. Each one runs as is.
pip install togetherexport TOGETHER_API_KEY=your_key
from together import Together

client = Together()

resp = client.chat.completions.create(
    model="MiniMaxAI/MiniMax-M3.1-Flash",
    reasoning_effort="high",
    max_tokens=32000,  # thinking counts toward this
    messages=[{"role": "user", "content": "Build a landing page for a ski lodge"}],
)
print(resp.choices[0].message.content)
What it's good at.
Bug fixes and features
73.7%
on DeepSWE. Opus 5 scores 74%.
Agents and tool calls
76.2
on BankerToolBench, level with Opus 5.
Landing pages and UI
1.4¢
the average cost of our 11 arena builds.
Long docs, images, video
1M
tokens of context at one flat price.
Try M3.1 Flash.
MiniMaxAI/MiniMax-M3.1-Flash